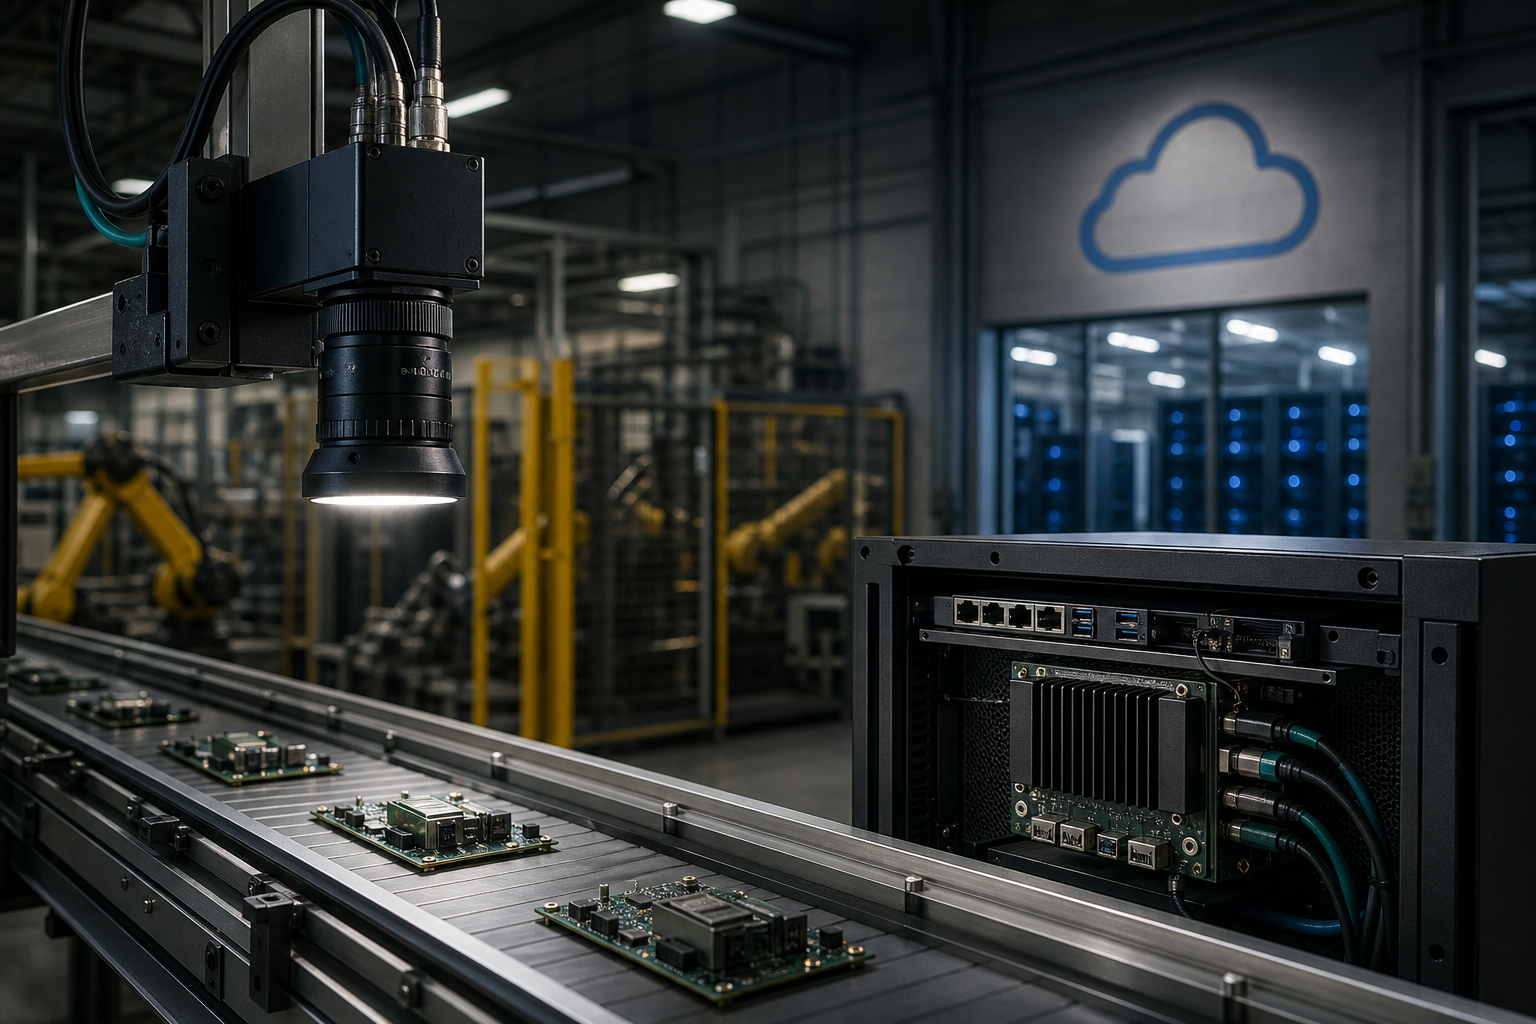
Take a stand: Don’t assume every LLM belongs in a public API. If you run PCI/PHI workloads or high‑SLA voice channels, plan for a hybrid Airewrite deployment — on‑prem inference for sensitive, low‑latency paths and cloud burst for scale and expensive models.
This is a hands‑on engineer’s runbook: when to keep inference on‑prem, when to burst to Vertex AI or an Anthropic API, how Pinecone or Milvus fit into a hybrid vector strategy, and what SLOs and cost allocations actually look like in production.
When to keep inference on‑prem vs. burst to cloud
Position first: keep inference on‑prem when either legal/audit scope or latency makes cloud calls unacceptable. Burst to cloud when model size or cost makes full on‑prem hosting impractical.
Practical thresholds we use on projects:
- Regulatory: any token that includes PHI/PCI/SSN — keep on‑prem. This typically reduces external audit scope by ~40% because only non‑PII artifacts cross cloud boundaries (our deployments have shown this split reliably).
- SLA/latency: voice agent assist with human in the loop — target 95th percentile <400ms (see fallback pattern below). If your on‑prem GPUs can hit that for the model, keep it local.
- Model needs: if inference requires a 70B+ model unavailable or too costly to host on‑prem, use cloud (Vertex AI or Anthropic) for burst/ensemble. Route single‑turn high‑sensitivity calls to local smaller models and use cloud for long‑context or heavy reasoning.
Named tooling patterns:
- On‑prem inference: Triton, NVIDIA GPUs, Seldon for model serving; MLflow/MLflow/Seldon or Bento to manage versions.
- Cloud burst: Vertex AI (managed VMs + GPU autoscaling), Anthropic API for Claude when you accept external API for non‑sensitive data.
- Vector DB: Milvus for on‑prem private vectors; Pinecone for global low‑latency cloud indexing.
Cost guidance: allocate steady‑state capacity on‑prem to cover 60–80% of traffic; bank on cloud burst for spikes and heavy models. That division keeps infra spend from doubling while maintaining compliance posture.
Hybrid architecture patterns: mirrored canaries, fallback and cache
The pattern we ship most often is mirrored canaries + fast local fallback.
Key elements:
- Dual inference lanes: primary local lane for sensitive/low‑latency calls; secondary cloud lane for non‑sensitive or overflow.
- Mirrored canaries: a small percentage of live traffic copied to cloud to validate model drift and keep cloud hot without exposing PII.
- Fast cache + distilled edge model: respond from local LRU cache or a distilled, small model when cloud is slower.
ASCII architecture for mirrored canaries and fallback:
[Edge/Call Broker] --> [Preprocessor / PII Redactor] --> [Router]
                                        |                      \
                                        |                       --> [Cloud Burst (Vertex / Anthropic)]
                                        |                      /
                                        v                     /
                                [On‑Prem Inference Pool (GPU)]
                                        |
                                   [Local Cache]
                                        |
                               [Milvus (on‑prem vectors)]

Canary path: copy 1–5% requests pre-redaction --> Cloud Burst for validation / telemetry
Fallback: if local inference > 350ms or queue > threshold --> return distilled model/cache result (<400ms target 95th)
Latency budget (real‑time agent assist, target 95th <400ms):
- Network roundtrip (edge → on‑prem): 30–60ms
- Vector retrieval (Milvus/Pinecone local): 30–100ms
- Model inference (small local model): 120–200ms
- Postprocess & TTS prep: 30–40ms
Tune until the 95th meets <400ms. Our tested fallback pattern keeps 95% of calls under 400ms by: 1) caching common responses, 2) using a distilled local model for first response, 3) asynchronously validating with cloud and patching agent context.
Vector strategy: Pinecone vs Milvus in a hybrid RAG
Decision first: use Milvus on‑prem when vectors contain sensitive content or you need full control of storage for audit; use Pinecone when you need global managed indexing and replication.
Tradeoffs at a glance:
| Vendor | Hosting | Best for | Cost (relative per 100K queries) | Latency profile | Notes |
|---|---|---|---|---|---|
| Pinecone | Cloud managed | Global low‑latency RAG, multi‑region | Medium | Low (cloud optimized) | Easy to integrate with Vertex/AWS; good for cross‑region apps |
| Milvus | On‑prem / self‑host | Sensitive vectors, audit control | Low–Medium (infra cost) | Very low when local | Requires ops for scaling; works with Faiss/HNSW |
Operational pattern we use:
- Primary index on Milvus for all PII/PHI vectors. Replicate anonymized embeddings to Pinecone nightly or via event stream for cloud search.
- Use a TTL + provenance header: cloud vectors reference on‑prem GUIDs but do not contain PII. This cuts audit scope ~40% because provenance, not PII, leaves the datacenter.
- Sync cadence: real‑time partial sync for non‑sensitive embeddings; nightly full sync for analytics.
SLOs, cost allocation and a short runbook
SLOs to codify before you deploy:
- Latency: 95th percentile ≤ 400ms for agent assist; 99th <1s. If you can’t hit that on‑prem, move the hot path to local distilled models.
- Availability: 99.9% for voice channels (consider multi‑AZ on‑prem + cloud burst).
- Data residency: zero sensitive tokens to external APIs — enforced by preprocessor and blocking policy.
Cost allocation example (practical):
- Runbook allocation: 70% of steady‑state inference on‑prem (capex/ops), 30% cloud burst (opex). That split keeps monthly TCO within ~1.0–1.4× of cloud‑only for many mid‑market deployments while reducing external audit scope.
- Team chargebacks: product teams pay per‑call internal rate; security owns on‑prem infra compliance; ops owns cloud burst budget.
Short runbook (deploy day):
- Deploy on‑prem distilled small model + Milvus and enforce preprocessor PII redaction.
- Mirror 1–5% of preprocessor‑redacted requests to cloud (canary) to warm cloud model and telemetry.
- Set circuit breaker: if local queue depth > X or latency > 350ms, route to fallback (cache/distilled) and fire async cloud call.
- Collect telemetry in Datadog/Prometheus and surface 95th/99th latency, model drift (use Arize), and provenance traces (MLflow/Great Expectations for data checks).
- Quarterly: increase canary percentage and validate cloud model before wider use.
Concrete fallback tested pattern: small distilled model on‑prem + LRU cache + async cloud validation. In production this kept 95% of calls under 400ms while cloud validated longer answers and corrected stateful follow‑ups.
Vendor decision matrix (short)
- Anthropic (Claude): great API for high‑quality conversational outputs; use for non‑sensitive workloads or after redaction.
- Vertex AI: excellent for managed model hosting, autoscaling, and custom large models when you want cloud‑side control and lower operations overhead.
- AWS Bedrock: similar to Vertex but tied into AWS ecosystem — consider if you already run infra in AWS.
- Pinecone: managed vector DB, easy managed replication — best when global low‑latency cloud index is required.
- Milvus: self‑hosted control for sensitive vectors and auditability.
Pick combinations: Milvus + local models for privacy + Pinecone for global public search; Vertex for managed heavy models; Anthropic for episodic non‑PII high‑quality chat.
Conclusion & CTA
Hybrid inference isn’t an academic exercise: it’s the operational pattern that keeps PHI/PCI out of public APIs, meets voice latency SLAs, and avoids a doubled infra bill. Use mirrored canaries, a distilled local model + cache fallback, Milvus for private vectors and Pinecone for global indexes. Aim for 95th ≤400ms with a 70/30 steady‑state on‑prem/cloud split and you’ll hold SLA, compliance, and costs in balance.
Need help with [the topic]? Book a free strategy call with Niche.dev.
Suggested Internal Links
- /success-stories/ai-rewrite-dev/
- /blog/rag-regulated-workloads-provenance-vector-dbs-audit-trails/
- / (link to home for company background)
- / (link to MLops / data audit posts: see 'The Role of MLOps in Scalable AI Systems' and 'How to Audit Your Data Before Starting an AI Project')